Skip to content
Stefano Tommesani

  • Home
  • Programming
    • SIMD on x64/x86
    • Multi-thread
    • C# and .NET
    • Testing
  • Software
  • Video
  • Marketing
  • About me
  • Home
  • Programming
    • SIMD on x64/x86
    • Multi-thread
    • C# and .NET
    • Testing
  • Software
  • Video
  • Marketing
  • About me
  • SIMD on x64/x86

    SSE3: the small SIMD extension that made horizontal operations easier

    June 24, 2020

    SSE3 is one of the easiest SIMD instruction sets to misunderstand. Compared with MMX, SSE, and SSE2, it did not introduce a new vector register file, it did not widen vectors beyond 128 bits, and it did not radically change the programming model. Instead, SSE3 added a small set of…
    Continue Reading
  • MedianValue
    GPGPU - SIMD on x64/x86

    Comparing SSE2 and GPGPU C++ AMP

    May 20, 2013

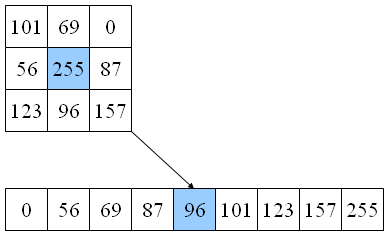
    The temporal median algorithm compares the same pixel in consecutive images in a sequence, and returns the median value of the pixel, i.e. the pixel value that has the same number of lower and higher values (an easy way to visualize this is imaging all the pixel values in an…

    Continue Reading
  • SIMD on x64/x86

    SSE2 Intrinsics: double-precision and integer SIMD programming

    May 27, 2010

    SSE2 extends the original SSE instruction set with support for double-precision floating-point arithmetic and a wider set of integer SIMD operations. The original SSE instructions operate mainly on four 32-bit single-precision floating-point values stored in a 128-bit XMM register. SSE2 adds the ability to operate on two 64-bit double-precision floating-point…

    Continue Reading
  • SIMD on x64/x86

    SSE Intrinsics: a practical guide to __m128 SIMD programming

    May 27, 2010

    SSE, short for Streaming SIMD Extensions, is an x86 instruction set extension that allows one instruction to operate on multiple floating-point values at the same time. The most common SSE programming model uses 128-bit XMM registers. Each register can hold four 32-bit single-precision floating-point values: Instead of adding one float…

    Continue Reading
  • SIMD on x64/x86

    MMX Intrinsics: Packed Integer SIMD with __m64

    May 27, 2010

    MMX was Intel’s first widely used SIMD extension for x86 processors. It introduced packed integer operations, allowing one instruction to process multiple small integer values at the same time. MMX is mostly historical today, but it is still useful to understand older multimedia, image-processing, audio, codec, and game code. Many…

    Continue Reading
  • SIMD on x64/x86

    SSE Arithmetic Instructions: packed and scalar floating-point operations

    April 24, 2010

    SSE arithmetic lets one instruction operate on four 32-bit floating-point values packed in a 128-bit XMM register. This page explains the arithmetic instructions, their C/C++ intrinsics, the difference between packed and scalar forms, and the practical pitfalls that matter when writing or reading SSE code. Packed vs scalar: PS and…

    Continue Reading
  • SIMD on x64/x86

    SSE2 and MMX: How 128-bit Integer SIMD Replaced Legacy MMX

    April 24, 2010

    MMX was Intel’s first widely adopted SIMD instruction set on x86 processors. It introduced 64-bit packed integer operations and made it possible to process multiple bytes, words, or doublewords with a single instruction. For the late 1990s, MMX was an important step forward. It was useful for image processing, audio…

    Continue Reading
  • SIMD on x64/x86

    MMX Shift Instructions: Logical, Arithmetic, and 64-bit Shifts

    April 24, 2010

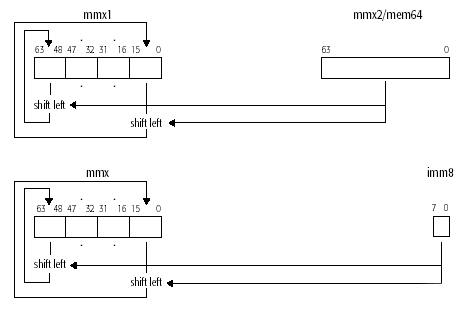
    The logical shift left, logical shift right and arithmetic shift right instructions shift each element by a specified number of bits. The logical left and right shifts also enable a 64-bit quantity (quadword) to be shifted as one block, assisting in data type conversions and alignment operations.   PSLLW mm,…

    Continue Reading
  • SIMD on x64/x86

    MMX Logical

    April 24, 2010

    PAND mm, mm/m64 PANDN mm, mm/m64 POR mm, mm/m64 PXOR mm, mm/m64 The PAND (Bitwise Logical And), PANDN (Bitwise Logical And Not), POR (Bitwise Logical OR), and PXOR (Bitwise Logical Exclusive OR) instructions perform bitwise logical operations on 64-bit quantities. The destination operand is an MMX register, while the source…

    Continue Reading
  • SIMD on x64/x86

    MMX Programming Examples: Masks, Packing, and Packed Integer tricks

    April 24, 2010

    This section describes example uses of the MMX instruction set to implement basic coding structures. Conditional Select Operating on multiple data operands using a single instruction presents an interesting issue: what happens when a computation is only done if the operand value passes some conditional check? For example, in an…

    Continue Reading
 Older Posts
Newer Posts 

Recent Posts

  • AltaLux 3.0: choose what to enhance
  • From API dependencies to portfolios of Suppliers
  • How benchmarks guided Codex to faster kernels in AltaLux V2
  • AltaLux 2.0: a new multiscale engine and a simpler way to enhance images
  • Terminal thinking

Downloads

Icon
AltaLux v. 3.0.2 plugin for IrfanView – Segmentation add-on installer
0.00 KB 1 file(s)
Icon
AltaLux v. 3.0.2 plugin for IrfanView – Segmentation add-on
0.00 KB 1 file(s)
Icon
AltaLux v. 3.0.2 plugin for IrfanView - x86 version
0.24 KB 1 file(s)
Icon
AltaLux v. 3.0.2 plugin for IrfanView - x64 version
0.24 KB 1 file(s)
Icon
Vigilo 0.9.0
0.00 KB 1 file(s)

Vintage CPUs of the day

  • Pentium 4 1.5 GHz Pentium 4 1.5 GHz
  • Intel 486DX2 50 MHz Intel 486DX2 50 MHz
  • Intel Pentium III on Slot 1 adapter Intel Pentium III on Slot 1 adapter
  • AMD Athlon XP 1700+ AMD Athlon XP 1700+

Categories

  • Audio
  • C# and .NET
  • GPGPU
  • Marketing
  • Multi-thread
  • OOD / OOP
  • Programming
  • SDLC
  • SIMD on x64/x86
  • Software
  • Testing
  • Uncategorized
  • Various
  • Video
  • Web
  • Web
© 2026 Stefano Tommesani. All rights reserved.
Graceful Theme by Optima Themes